Topic
Frontier Models
9 stories on this topic, newest first.
Claude Fable 5.2 for builders: when to route past Opus 5.5, and what it costs
Fable 5.2 costs $8/$40 per million tokens, twice Opus 5.5. What Anthropic's data says it buys, plus fast mode, advisor rules and the preserved-thinking break.
Gemini 4 Carbon goes public, and its introductory price ends 30 November
Google's strongest model costs $2/$10 per million tokens until 30 November, then $4/$20. How to budget the switch, what /swarm does, and the #1 claim today.
ResearchAnalysis
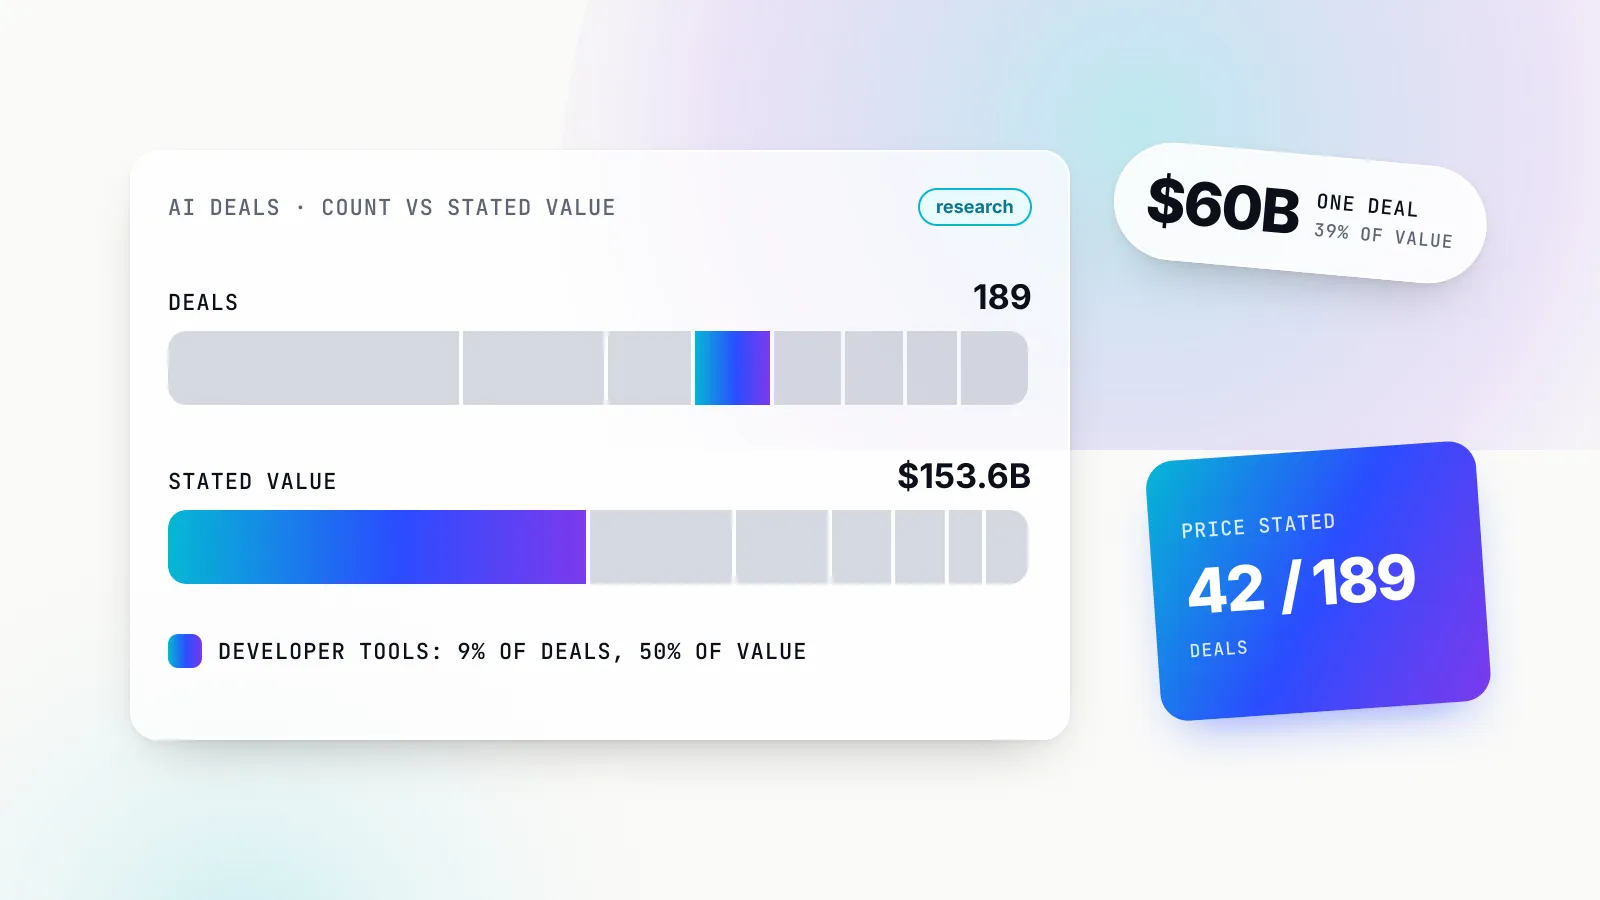
Developer tools drew half of all stated AI deal money from 9% of deals
We analysed 189 AI deals since January 2025. Developer tools took $76.3B of the $153.6B in stated prices, one deal is 39% of it, and only 16 prices came from the companies.
ModelsExplainer
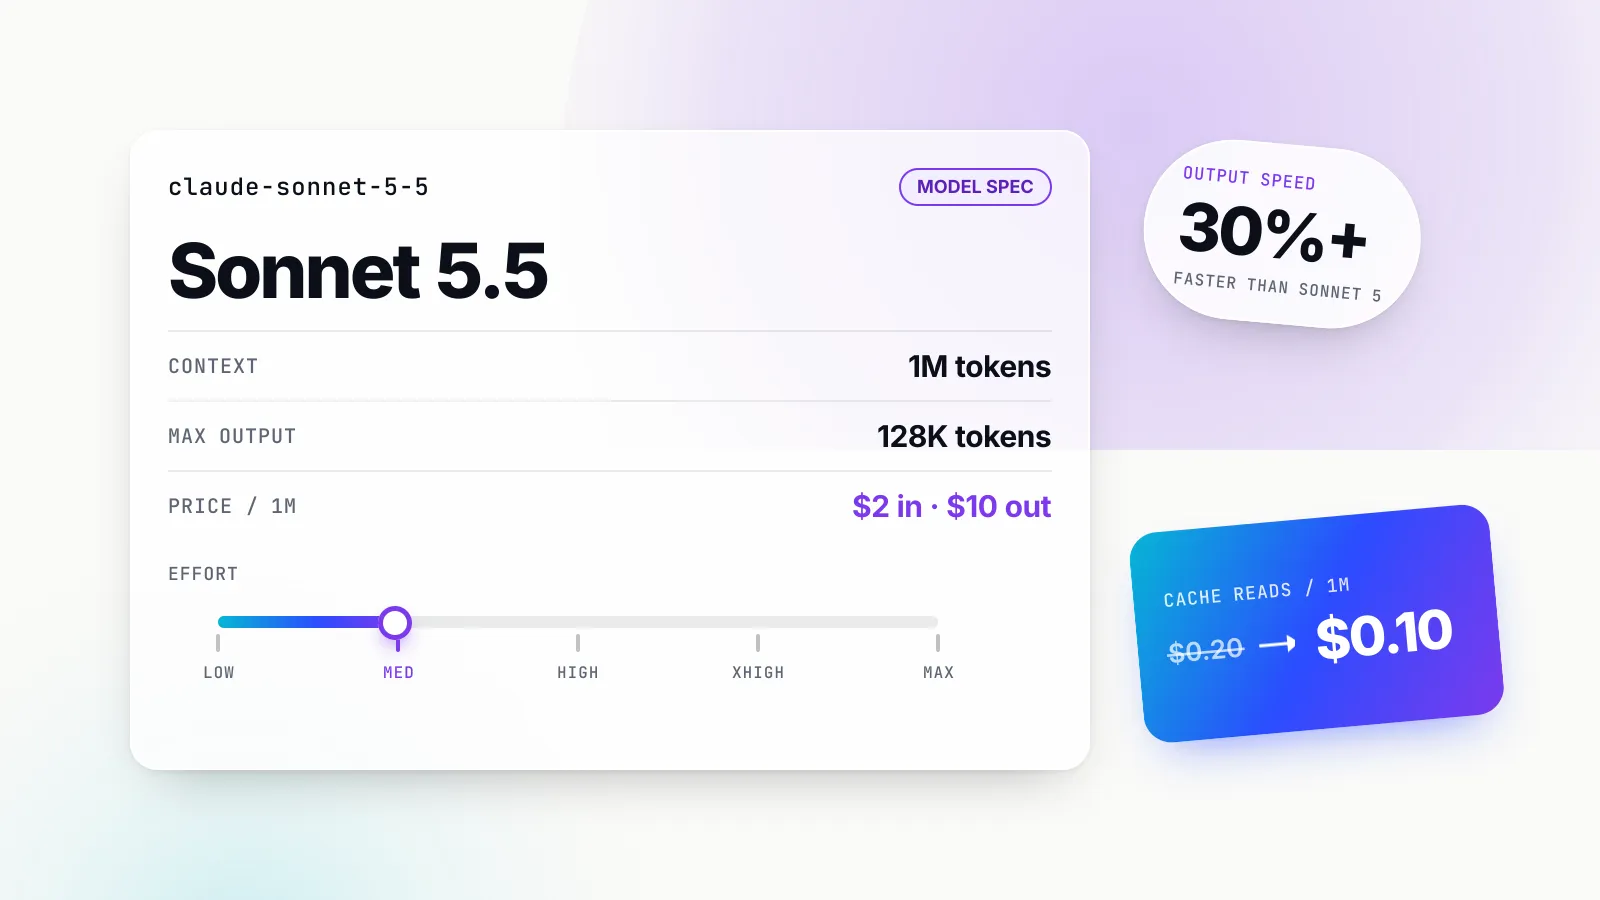
Claude Sonnet 5.5: a practical guide to price, effort, benchmarks and migration
Anthropic's mid-tier model costs $2 in and $10 out per million tokens with a 1M context. What changed from Sonnet 5, when to pick it over Opus 5.5 or Haiku 5.5, and how to migrate.
ModelsComparison
Best LLM for coding in October 2026: ten models ranked on the evidence
Opus 5.5, GPT-6.1 Sol, Gemini 4 Argon and seven more ranked on Terminal-Bench 4.0, DeepSWE and cost per task, with each score's harness and source.
ModelsComparison
Top 10 AI models in October 2026, ranked by what they are good at
Claude Opus 5.5, GPT-6.1 Sol, Gemini 3.8 Flash, Kimi K3 and six more, ranked on independent evals, coding, context, price and speed, with every figure sourced and dated.
NewsAnalysis
Inference prices keep falling. Here is who actually keeps the saving
Same-capability inference gets 9 to 900 times cheaper a year, per Epoch AI. Whether your bill shrinks depends on tokens per task, caching and lock-in. Twelve models priced as of September 2026.
ModelsExplainer
How to read a model card without being fooled: the 2026 field guide
System cards now run past 200 pages. We take five current cards apart section by section, show how one benchmark is reported five different ways, and set out a ten-step reading protocol.
ModelsAnalysis
Open weights trail the frontier by months. The economics say the gap will not close
Epoch AI measures the lag at four months; Stanford's AI Index puts it at 3.3% on Arena. Who pays for frontier runs, who gives weights away and why, and what that means for builders.